
HUMAIN colabora con Compal para impulsar la expansión de la IA de la nube al borde
Source: PR Newswire
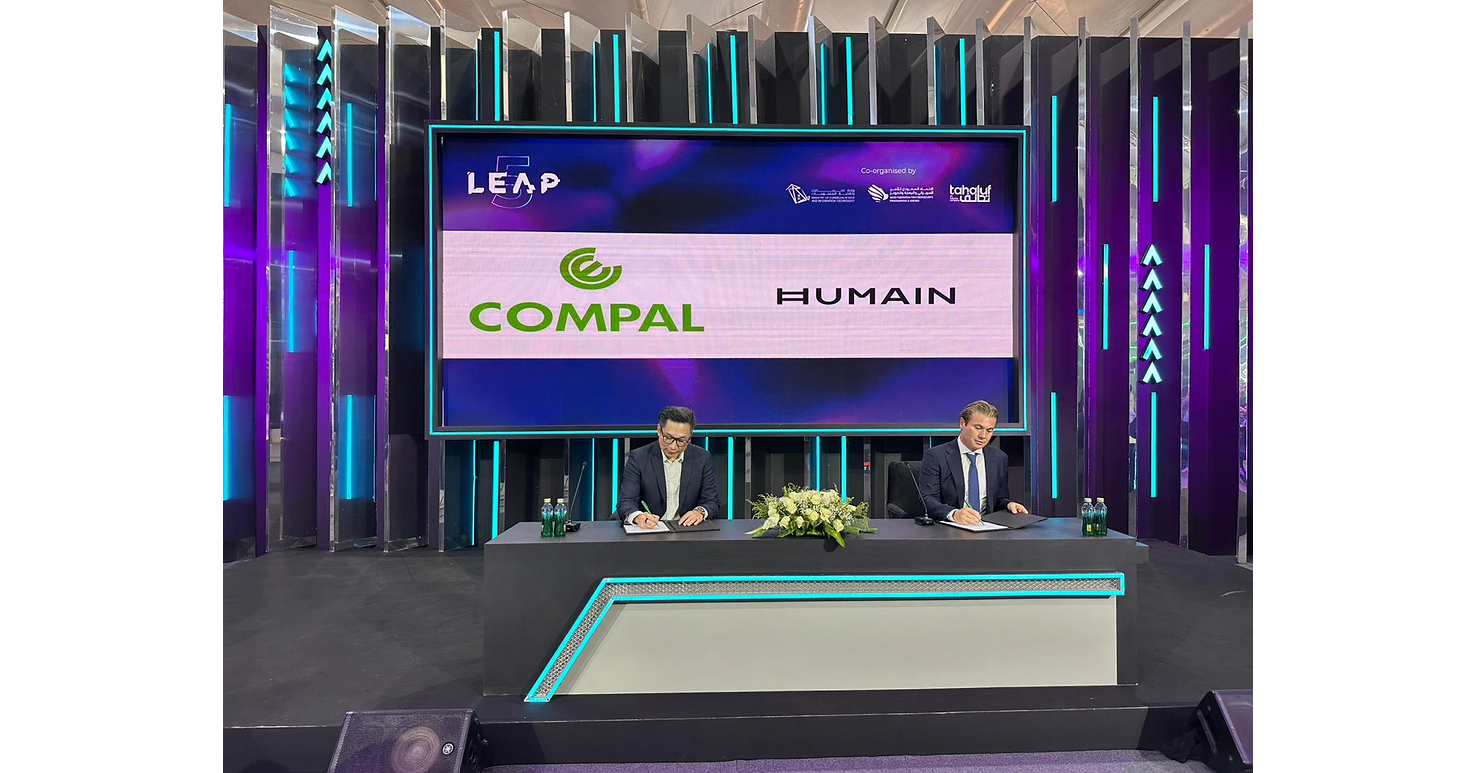
HUMAIN anunció una alianza de largo plazo con Compal para impulsar la infraestructura de IA “de la nube al borde”, incluyendo servidores de IA y plataformas de computación perimetral. El acuerdo contempla el desarrollo de múltiples generaciones de infraestructura de IA para cargas de entrenamiento e inferencia, apoyándose en tecnologías de aceleración de NVIDIA y AMD, y la extensión a PCs con IA y “IA física” aplicada a hospitales (ej. PolyMedX con NVIDIA Agent-Ready Rheo Blueprint). El anuncio, presentado en LEAP 2026, refuerza la estrategia de HUMAIN para desplegar capacidades de IA en entornos reales y consolida el rol de Compal como socio ODM.
Analysis
This reads more like a validation signal than a revenue event. The important mechanism is that a PIF-backed buyer is formalizing a multi-year path from cloud to edge/physical AI, which supports the idea that sovereign demand can become a recurring infrastructure funnel rather than a one-off pilot cycle. For NVDA and AMD, the near-term impact is mostly sentiment and backlog optionality; the actual earnings contribution likely lags by 2-4 quarters and depends on whether the program converts into repeat server refreshes.
Competitive dynamics favor NVDA on quality-of-demand, even with AMD included. Sovereign customers usually optimize for deployment speed, software maturity, and supply assurance, so NVDA should capture the higher-probability share of accelerator spend, while AMD benefits more from the strategic need for second-source diversification and price/performance competition. The second-order winners are ODMs and the power/thermal ecosystem; edge and physical AI broaden unit counts, but those deployments are typically less GPU-dense than training clusters, so headline enthusiasm can overstate dollar intensity.
The contrarian risk is that this becomes another press-release-driven AI umbrella story with limited measurable pull-through. If upcoming Compal/partner earnings do not show backlog conversion, the market will likely fade the read-through; likewise, if NVDA/AMD commentary stays focused on hyperscaler training while ignoring sovereign/edge demand, the thesis weakens. Over 6-18 months, the structural upside is real if sovereign AI budgets scale, but the path is slow, procurement-heavy, and vulnerable to capex delays, making this more of a selective infrastructure signal than a broad semiconductor catalyst.
AllMind Terminal
AI-powered research, real-time alerts, and portfolio analytics for institutional investors.
Request TrialMarket Sentiment
Overall Sentiment
mildly positive
Sentiment Score
0.25
Ticker Sentiment
Key Decisions for Investors
- Maintain a modest tactical long NVDA for 1-3 months as a confirmation trade on sovereign AI demand; prefer stock over calls because the catalyst is conversion risk, not a binary event.
- Keep AMD on watch rather than chasing the headline; only add if subsequent channel checks or management commentary show actual sovereign/server share gains, otherwise the stock is just higher-beta narrative exposure.
- Pair trade: long NVDA / short SOXX on sector pullbacks, using this as a relative-strength expression that benefits if sovereign AI demand proves real while the broader AI hardware basket mean-reverts.
- Set a catalyst alert for upcoming ODM and supplier earnings; if Compal-style programs do not show backlog or margin improvement within 1-2 quarters, reduce any long exposure because the story is likely sentiment-only.
More News
- Why did CoreWeave stock get crushed this week? Look to this corner of the debt market for clues
- AI stock sell-off ramps up over debt-fueled data center spending fears: ‘Full-blown crisis of confidence'
- We're downgrading this retail stock after a big comeback. Plus, AI names slide again
- Why is VanEck Semiconductor ETF sliding today?
- I watched Nvidia's Jensen Huang work the room in London. He brought big checks — and a blunt message
- Benchmarked: Nvidia's RTX Spark notebook delivers serious local AI compute, at a price